Pipelines, evaluation and monitoring for LLM and ML systems in production.
Mindrops builds the pipelines, evaluation, deployment and monitoring that take LLM and ML prototypes into production, with versioned releases, quality gates and cost tracking.
A selection of the software Mindrops has designed and engineered for clients.
AI · ML
AI-Based Product Development
Mindrops built four production ML products in Python: predictive maintenance, computer-vision body measurement, multi-channel attribution and deep-learning manpower forecasting.
25% lower maintenance cost, 20% fewer sales returns, 15% more sales and 90% better forecasting accuracy for the respective clients.
Cafés in India50+outlets across India, served by the systems we builtBrewing since 1963
AI · Food & Beverage
BeanBot — The Coffee Bean & Tea Leaf
An embeddable AI chat assistant grounded in live catalogue and store data, with an “Order Now” action on every product and a no-code admin console for content and pricing.
Live across 50+ outlets in India, handling about 10,000 conversations a month and around 50 orders a day.
Total post offices1,65,000The largest postal network in the world
Government · GovTech
India Post — Grievance Redressal
An AI-automated platform on Mindrops’ LazyMonkey foundation that categorises, prioritises, routes and auto-responds to every grievance, with one SLA-tracked record for central and regional teams.
Awarded via GeM (Nov 2025), it auto-triages thousands of grievances a day for a network of 1.5 lakh+ post offices.
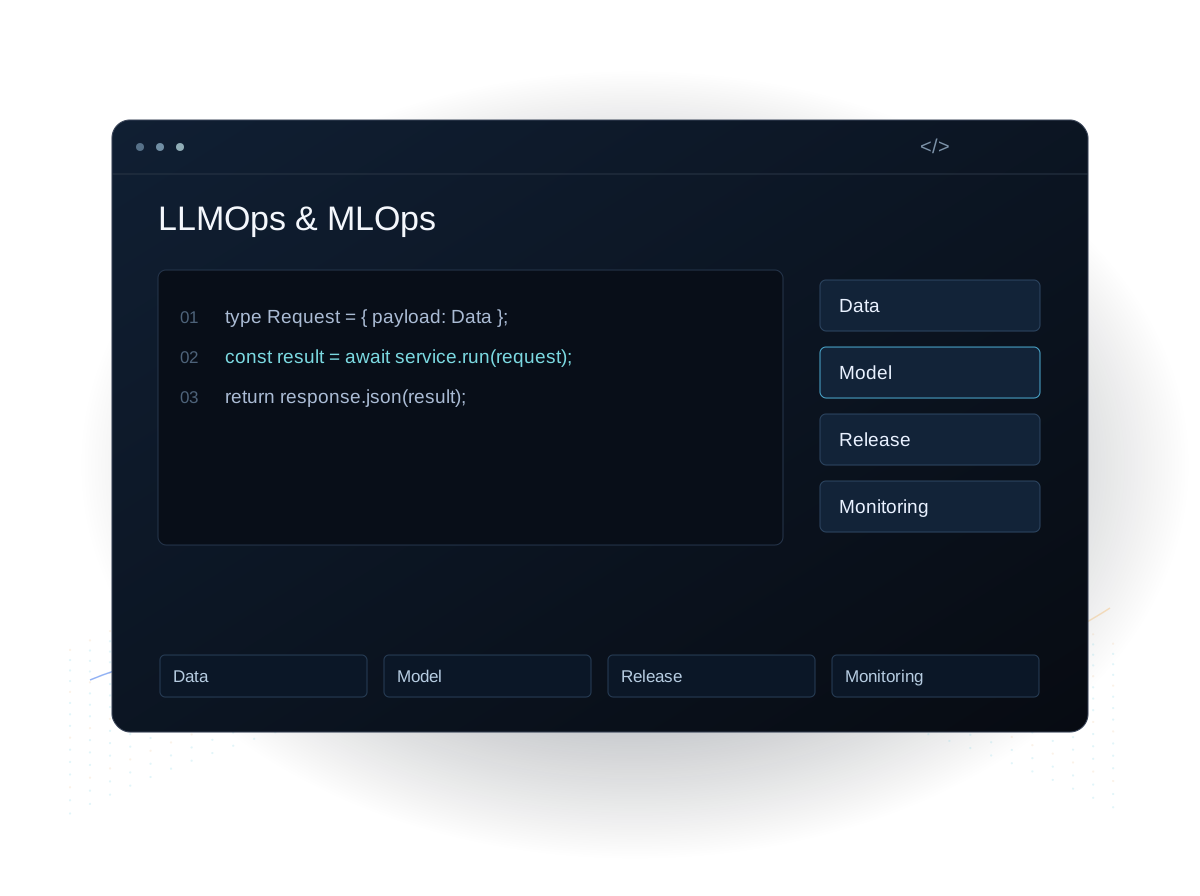
Mindrops builds and runs the LLMOps and MLOps lifecycle that takes machine-learning and large-language-model systems to production reliably — data and training pipelines, evaluation, deployment, monitoring and cost control. The result keeps AI accurate, observable and economical once it is live.
01
Pipelines & automation
Reproducible data, training and inference pipelines with versioning and CI/CD for models and prompts.
02
Evaluation & testing
Automated evals, regression tests and quality gates so every change ships with test results.
03
Deployment & serving
Scalable, low-latency model serving — managed APIs, self-hosted or hybrid to meet data-residency needs.
04
Monitoring & drift
Production monitoring for quality, latency, drift and hallucination, with alerting and tracing.
05
Cost & performance
Token, caching and routing strategies that keep AI fast and economical at scale.
06
Security & governance
Access control, secrets, audit and guardrails wired into the pipeline from day one.
Who needs LLMOps or MLOps
Teams with a prototype in a notebook
A model or LLM app works in a notebook but has no pipeline, tests or monitoring. We build the path to a dependable release.
AI products with rising inference bills
Token spend grows faster than usage. Routing, caching and model selection bring cost back under control without losing quality.
Data science teams deploying by hand
Models are retrained and released manually, and nobody is sure which version is live. Versioned pipelines and CI/CD fix that.
Owners of models that drift
Forecasts and classifiers quietly lose accuracy as data changes. Drift monitoring and scheduled retraining catch it early.
Why Mindrops for LLMOps and MLOps
Classical ML in production
We have built and shipped forecasting, anomaly-detection, computer-vision and attribution models — including an LSTM manpower forecast that looks 30 days ahead for a power-distribution company.
Cost designed in from day one
BeanBot routes button taps and menu queries away from the model entirely and sends only open-ended questions to an LLM — the routing discipline we bring to every LLM system.
Observability per request
Step-by-step traces, token usage and outcome analytics on every interaction, so quality and cost regressions show up on a dashboard as they happen.
Ops and cloud under one roof
Our SRE and managed-cloud teams run the serving infrastructure, so model pipelines inherit the same alerting, backups and access control as the rest of your stack.
Technologies we use
LLM & ML
OpenAI / LLMs · Anthropic · RAG · PyTorch
Pipelines & serving
Docker · CI/CD · Vector DBs · Serverless
Observability
Tracing · Evals · Drift detection · Dashboards
Cloud
AWS · Azure · GCP
Client reviews
Extra capacity for software and cloud
A Mindrops team working alongside the client’s own engineers on software development and cloud-based projects, brought in to add reliable delivery capacity.
From the client’s review
“Mindrops handled complex requirements with ease and added value throughout the project.”
MLOps covers the lifecycle of machine-learning models; LLMOps applies the same discipline to large-language-model systems — prompts, retrieval, evals and token cost. Mindrops does both, end to end.
A prototype works but is unreliable in production. Can Mindrops help?
Yes — that is exactly this service. Mindrops adds pipelines, evaluation, monitoring and guardrails so the system behaves predictably and regressions are caught before users see them.
Can Mindrops control AI running costs?
Yes. Mindrops applies caching, routing, model selection and token strategies, and monitors spend, so quality stays high while cost stays controlled.
Can models be self-hosted for data residency?
Yes. Mindrops deploys managed, self-hosted or hybrid serving depending on latency, cost and data-residency requirements.
How does this relate to governance?
LLMOps implements much of what AI governance requires — evals, monitoring and audit — as running infrastructure.
Contact us
Tell us what is in production, or stuck before it. We’ll map the gaps in your pipelines, evals and monitoring, and reply within one business day.